
Content Moderation & RLHF Services for Safer AI
Improve the safety, quality and alignment of your AI systems with managed content moderation and RLHF services. Our trained annotators and domain experts evaluate, rank, rewrite and moderate model outputs for LLMs, VLMs, RAG systems and AI agents.
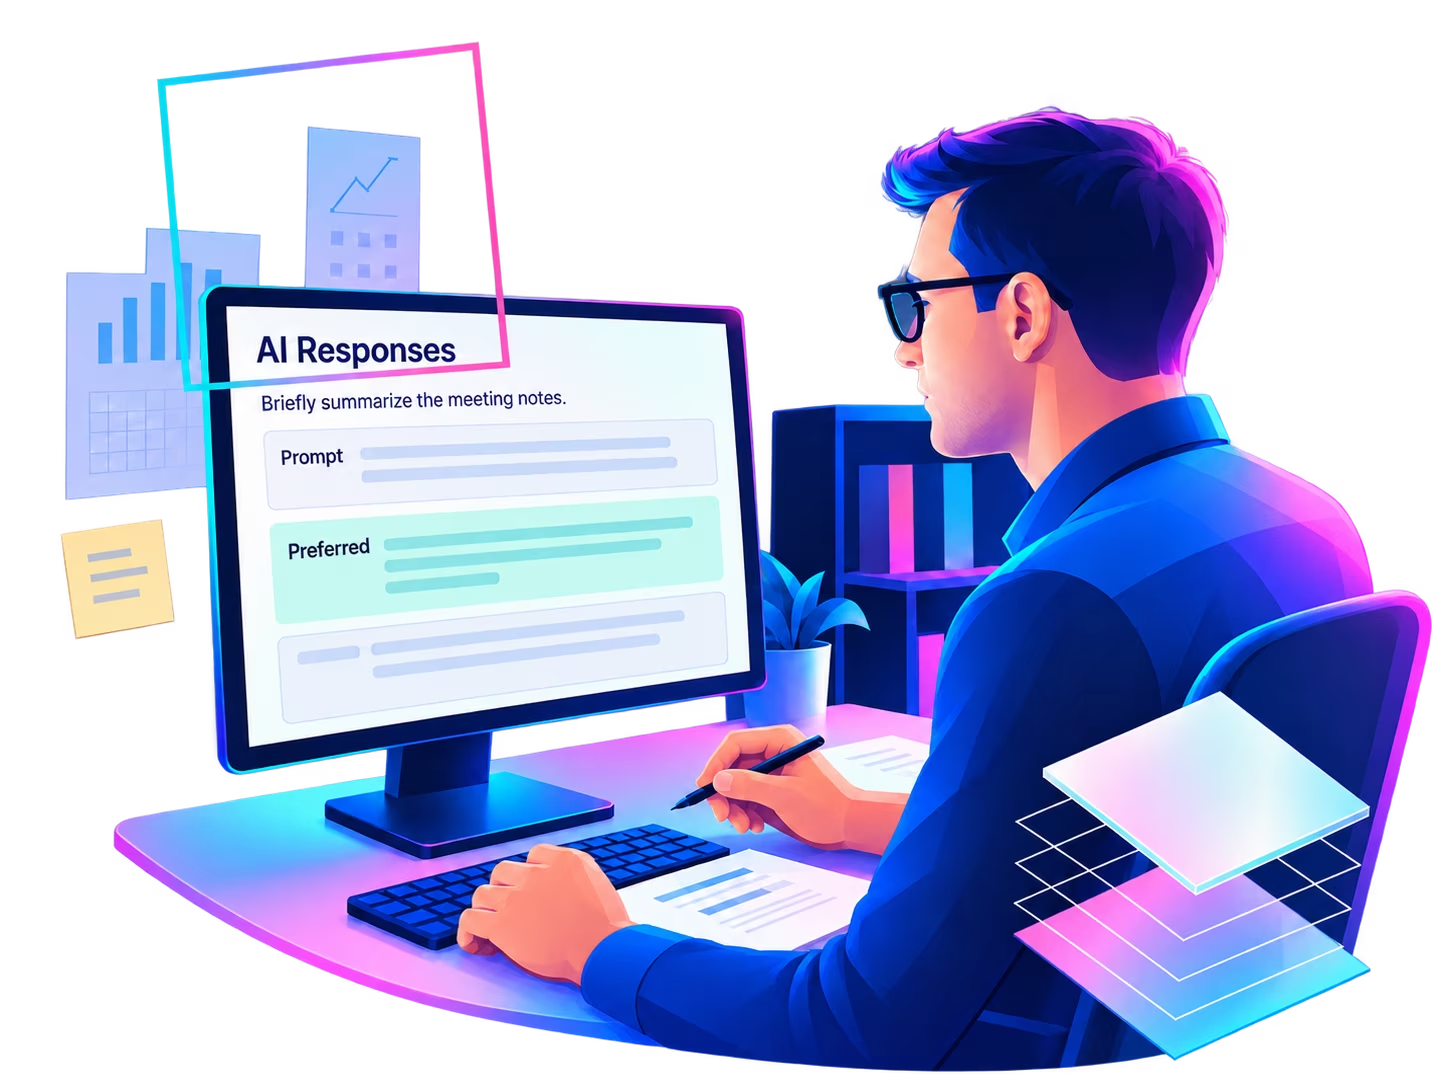



Human feedback is essential to building safer, better-aligned AI. Our teams moderate sensitive content, rank model responses, annotate human preferences and review outputs against your quality, safety and compliance criteria.
AI Content Moderation Services
RLHF Services
AI Safety & Compliance
Domain-Specific Moderation
AI Content Moderation Services
Protect users and improve model quality with human-led AI content moderation services. We identify, classify and review harmful, inappropriate, biased or non-compliant outputs across text, image, audio and multimodal systems, using guidelines tailored to your domain, languages and risk thresholds.

Detecting hate speech
Identify, annotate, and filter content generated by AI models that include violent, discriminatory or hostile speech targeting groups or individuals.
Manual or assisted annotation of AI answers containing problematic remarks
Fine classification of the types of hate speech (direct, implicit, inciting, humorous, etc.)
Construction of data sets for training or evaluating automatic filters
Quality review by annotators trained in context detection
Chatbots & AI assistants — Automatic blocking or reformulation of high-risk generated responses
Pre-publication moderation — Monitoring of outputs generated by text-to-text or text-to-image models
Anti-toxicity filter training — Improving conversational safety in AI systems

Inappropriate content
Locate, annotate, and control responses produced by AI systems that may contain shocking, offensive, vulgar or contextually inappropriate material.
Definition of risky content categories (vulgarity, suggested nudity, sensitive remarks, sexual insinuations, etc.)
Manual or semi-automated review of AI responses generated in different contexts
Annotation of severity levels (mild, moderate, critical) and types of harm
Development of datasets to train content filters or scoring models
Text or image generation systems — Filtering NSFW or offensive content before posting
Conversational assistants — Preventing slip-ups in responding to ambiguous requests
AI products for the general public (young people, families) — Secure interactions for all ages

Human review of sensitive outputs
Submit answers generated by an AI in contexts to specialized annotators or moderators trained to handle signicant ethical, legal or reputational risks. This validation step ensures that the content delivered is appropriate, reliable and compliant, especially when they touch on critical areas.
Identification of sensitive scenarios (health, justice, religion, politics, gender, minors, etc.)
Human review with an evaluation grid: factual accuracy, tone, clarity, bias, potential danger
Annotation of levels of sensitivity or risk (erroneous information, tendentious comments, poorly formulated response, etc.)
Reporting or removing non-compliant content + reformulation if necessary
Regulated areas (finance, insurance) — Validation of AI content before publication or integration into a client tool
General chatbots — – Monitoring AI responses to sensitive or provocative prompts
Generative content moderation — Adding a level of human validation to sensitive interactions (“Human-in-the-Loop”)

Response toxicity scoring
Quantify the degree of harmfulness, aggressiveness or danger of a response generated by an AI model, in order to assess its relevance, to guide automatic moderation or to feed correction loops (RLHF, filtering, reformulation). This score provides an objective, repeatable measure of the safety and appropriateness of the generated content
Definition of a toxicity grid (violent, insulting, discriminatory, sarcastic language, etc.)
Human annotation of the responses generated, according to their tone, target and potential severity
Analysis of discrepancies between AI and human judgment to refine filtering models
Creation of labeled datasets to train or calibrate toxicity classifiers
AI assistant monitoring — Evaluate responses to sensitive or diverted prompts
Development of content filters — Feed models for detecting unacceptable speech
Online reporting tools — Improvement of moderation systems based on toxicity thresholds

Content categorization
Organize training data for AI or responses generated by an AI by thematic or functional categories (e.g. sports, politics, health, marketing, etc.), in order to facilitate their moderation, filtering, personalization, or analysis.
Definition of a category repository adapted to the use case
Manual annotation of AI responses according to the target classification (mono or multi-label)
Construction of labelled datasets for the training of supervised classifiers
Quality control covering inter-annotator agreement, ambiguous cases and overlapping categories
Structuring the corpora generated for analysis or evaluation — Thematic organization facilitated
Preparing for sectoral moderation — Identify answers in sensitive areas (legal, medical, etc.)
Benchmark of generative models — Measure the thematic distribution of the responses produced

Moderation of AI agents
Supervise, control and correct the behaviors or responses of virtual assistants (chatbots, voice assistants and copilots, etc.) to avoid drifts, biases or clumsiness in interactions with users.
Definition of moderation rules according to the context of use (sector, language, target, tone)
Monitoring AI conversations via targeted human review
Escalation of critical cases to human moderators (validation or correction)
Creation of training sets to refine model behaviors via RLHF or fine-tuning
Health or insurance agents — Verification that the AI does not issue medical or legal recommendations
Online assistants from top brands — Alignment of responses with brand tone and internal policies
Multilingual interactions — Verification of the coherence and neutrality of speech in each language
RLHF Services for LLM Alignment
Align your models with human expectations through managed RLHF services. Our trained evaluators rank responses, annotate preferences, rewrite outputs and create high-quality feedback datasets for reward modeling, preference optimization and continuous model evaluation.

AI response ranking
Present several responses generated by one or more models from the same prompt, and rank them according to their perceived quality. To identify the most useful, relevant, safe, or appropriate formulations, to feed both RLHF and DPO (Direct Preference Optimization) pipelines.
Manual annotation by trained moderators or annotators
Definition of preference criteria
Qualitative or comparative scoring
Quality control by double annotation or consensus
Reinforcement training (RLHF) — Creation of preference data to refine LLM behaviors
Construction of reference datasets — Create references to guide or evaluate other models
Linguistic or sectoral benchmarking — Compare the performance of models according to languages, styles or business areas

Annotating human preferences
Gather qualitative judgments from annotators on AI-generated responses, depending on what a human would deem to be most useful, clear, relevant, or appropriate. Allows you to train or adjust generative models according to real expectations and preferences of end users.
Selection or generation of several responses for the same prompt (two or more)
Presentation to a human annotator with preference instructions (quality, respect for the prompt, style, etc.)
Supervision by precise guidelines to avoid subjective biases
Quality control via double annotation or arbitration
RLHF model training — Integrate the human signal to guide generative behaviors
Customizing AI assistants — Adapt responses to a specific audience, style, or context
Continuous improvement of conversational AI — Integrate human feedback into learning cycles

Manual output review
Manually correct, rewrite or adapt the responses generated by an AI model, in order to guarantee a high level of quality, clarity, accuracy or adaptation to the context. This step is often used to build reference datasets (gold data or gold standard) or refine a model via supervised fine-tuning.
Selection of generated outputs requiring revision
Correction or rewriting of the answer by a human expert
Annotating the types of changes made
Use of before-and-after pairs for supervised training, evaluation, or documentation
Creation of supervised examples — Creation of “before-after” pairs to train models via direct supervision
Marketing — Stylistic correction of generated texts to respect the brand tone or target audience
Health — Review of AI responses to eliminate inaccurate formulations or formulations that do not comply with clinical recommendations

Data generation for RLHF
Create representative prompts and diverse model responses allowing models to be exposed to different formulations, levels of quality, or response styles. This data is then classified or evaluated by human annotators to guide reinforcement learning.
Manually creating prompts representative of target users
Verification of the diversity of the outputs produced (style, relevance, errors)
Preparation of pairs or lists to be classified by human annotators
Organization of the dataset for training: prompts + responses + human preferences
Optimizing conversational models — Creation of realistic scenarios to train models to respond better
Robustness of LLMs — Voluntary generation of chalenging, borderline and edge cases to detect faults and lead to safer behaviors
— Create varied interaction scenarios to improve response tone and relevance

Supervised fine-tuning
Refine a language model using a dataset containing prompt-response pairs with high-quality answers, validated or reviewed by humans. Allows you to specialize a model for a specific domain, to improve the quality of its answers, or to correct certain undesirable behaviors.
Definition of the target domain or the behaviors to be adjusted
Creation or selection of a corpus of annotated examples (prompt + validated response)
Cleaning, normalizing and structuring the data set (JSONL format)
Verification by human reviewers to ensure the quality of the corpus
Specialized health or pharmaceutical models — Training based on answers validated by professionals
Business chatbots — Fine-tuning with pre-written dialogues for a given sector (banking, HR, insurance...)
Multilingual fine-tuning — Adjustment of the model to languages that are not well covered thanks to supervised bilingual corpora

Comparing generative models
Test several models (or variants of the same model) on identical prompts, then to évaluonsassess their responses according to qualitative and quantitative criteria. To identify which model is the most suitable for a given use case, or to measure the gains of fine-tuning.
Selection of a panel of prompts covering several use cases or typical scenarios
Generation of responses from different models (e.g.: base vs fine-tuned, GPT vs Mistral)
Human annotation of responses according to defined criteria
Rating or scoring of answers (pairwise, best-of, rating scale)
Post-fine-tuning assessment — Check if a model refined on specific data outperforms its basic version
Multi-model benchmark — Compare several open source LLMs (Llama, Mistral, DeepSeek, and other open-source models) on target tasks
Assessment for audit or compliance — Document the behaviors of a model to meet regulatory requirements
AI Safety & Bias Evaluation
Assess the safety, fairness and traceability of your AI data and model outputs. We audit datasets, detect bias, validate sensitive content and document quality controls to support responsible AI and regulatory readiness.

Training dataset audit
Conduct an in-depth audit of a training dataset to assess its quality, representativeness, structure, potential biases and legal or ethical risks. To ensure that the foundations of the model are sound, reliable, and aligned with business and regulatory goals.
Analysis of the overall structure of the dataset
Detection of biases or imbalances
Identification of sensitive or risky content
Assessment of diversity and thematic coverage
Regulatory compliance (EU AI Act, GDPR, ...) — Verification that the dataset complies with transparency and ethical obligations
Algorithmic bias prevention — Identification of sources of unfairness or unbalanced representations in the data
Assessing the robustness of the data — Analyze whether the dataset covers critical or sensitive cases

Detecting biases in content
Spot the imbalances, stereotypes or problematic representations present in the data used to train or test AI models. This helps prevent discrimination, support responsible model use and meet compliance requirements.
Define the types of biases to monitor
Human annotation of problematic or ambiguous cases
Statistical evaluation of imbalances between categories or classes
Corrective recommendations (cleaning, balancing, exclusion, reformulation)
Educational evaluation of generative models — Verification of the fairness of the answers in educational or academic cases
Preparing fairness evaluation sets — Construction of scenarios to test the robustness of models in the face of biases
Blocking or reformulating risky content — Filtering generated outputs with implicit biases

Monitoring AI-generated data
Establish a human or hybrid review process for content produced by generative models (text, image, audio,...), in order to detect Inappropriate slip-ups, errors, biases, or content. This helps reduce reputational, legal and ethical risks.
Definition of surveillance rules and criteria (thematic, linguistic, ethical, etc.)
Extraction of representative samples or real-time monitoring of generated outputs
Human or automated analysis of AI responses (via scoring tools, alerts, reports)
Annotation of problem cases (hallucinations, toxic remarks, inaccuracies, stereotypes...)
Supervision of consumer chatbots — Continuous monitoring of responses to avoid inappropriate or offensive remarks
Monitoring of models in production — Verification that the answers remain consistent over time despite changes in use
Detection of sensitive or viral contents — Identification of potentially polarizing or problematic responses

Data diversity check
Analyze a training or test data set to ensure it covers a sufficient variety of themes, styles, languages, profiles, or viewpoints. This supports robust, inclusive and generalizable AI model performance.
Definition of the expected diversity criteria
Statistical and qualitative analysis of the dataset according to these criteria
Detection of imbalances or gaps (e.g. gender bias, lack of cultural variations, homogenous tone)
Enrichment recommendations (data addition, rebalancing, larger sampling)
Preparation of multilingual or multicultural datasets — Ensure that each language or culture is fairly represented
Training specialized models (health, education, etc.) — Verification that the profiles of patients, students or users are varied
Regulatory compliance (AI Act, diversity & inclusion) — Provide proof of verification work on the representativeness of the data

Manual data validation
Involve human annotators or reviewers to check, correct, or confirm the quality of textual, audio, visual, or tabular data, before or after their use by an AI model. This makes training datasets, evaluation sets and generated outputs more reliable.
Selection of data to be validated (random, critical, from an automatic pipeline, etc.)
Definition of validation criteria (accuracy, format, clarity, completeness, alignment, ...)
Human review or verification via annotation interface or control panel
Correction of identified errors or inconsistencies (faults, entities, formats, AI responses, ...)
Correction of OCR or automatically transcribed datasets — Human review to make the extracted data reliable
Validating multilingual audio transcripts — Verification by native speaker or linguistic expert
Quality control on test sets — Elimination of biases or errors in evaluation benchmarks

Dataset documentation
Provide a clear, complete and structured description the origin, content, characteristics, and limitations of a dataset intended for training or evaluating an AI model. This step is essential to guarantee the transparency, reusability, and compliance of the data used in a project.
Collection of information on the origin of the data (source, collection method, licenses, consent...)
Description of the characteristics of the dataset: data type, size, formats, formats, languages, classes, balance, anonymization...
Identification of usage goals (training, testing, fine-tuning, etc.) and reporting potential biases or limitations
Structured writing of documentation (e.g. datasheet, model card, AI inventory sheet)
Regulatory compliance (AI Act, GDPR, ...) — Provide formal and traceable documentation of the data used
Transparency in public or sensitive AI projects — Explain what a dataset contains and why it was chosen
Facilitating the reuse of internal datasets — – Clear transmission of proprietary (company-specific) or Open Source datasets to data or AI teams
Domain-Specific Content Moderation
Apply content moderation rules that reflect your business context. Our domain-trained reviewers evaluate AI outputs in regulated and high-risk environments, including healthcare, finance, legal services, customer support and multilingual applications.

Moderation in health, finance, law
Annotate, filter, and validate AI-generated data or responses to avoid factual error, misinterpretation, or risky recommendation. In these regulated contexts, the presence of human supervision is essential to support the compliance, reliability and safety of AI systems.
Definition of business rules and acceptability thresholds (tone, terminology, accuracy, etc.)
Proofreading and human validation by annotators trained in sectoral issues
Reporting or rephrasing non-compliant or ambiguous content
Traceability of human interventions for audit, compliance and continuous improvement
Finance — Verification of content related to taxation, investments or banking regulations
Law — Control of responses generated by legal models (clause, case law, advice) to avoid confusion or misinformation
Health — Human validation of AI responses in medical chatbots or clinical assistants

Content filtering
Identify, isolate, or remove content (training data or generated outputs) that are inappropriate, irrelevant, sensitive, illegal, or harmful to the quality or compliance of an AI project. It can be textual, audio, visual, or multimodal data. Filtering can be automated, manual, or hybrid.
Definition of filtering rules: forbidden topics, sensitive comments, language level, noise, duplicates, etc.
Human intervention for validation
Labeling rejected content
Updating rules and thresholds according to regulatory or business developments
Preparing training datasets — Elimination of toxic, ambiguous, redundant or irrelevant examples
Targeting sectoral corpora — Removal of data that is not relevant for training a specialized model (health, finance, etc.)
Blocking NSFW or sensitive content — Exclusion of content that does not conform to the final use of the model

Business workflows
Contextualizing human interventions in content production or decision workflows, in order to ensure business relevance, data quality, and compliance in AI-enabled workflows.
Definition of human roles in the loop: validation, filtering, enrichment, reformulation,...
Creation of customized workflows with escalations, trade-offs or trust thresholds
Integration into internal tools
Performance monitoring and continuous adaptation of the human role in the AI-augmented process
Legaltech — Workflow for double validation on legal clauses or recommendations proposed by AI
Documentary processing — Inclusion of reviewers in the OCR pipeline + data extraction for audit or contract
E-commerce & marketing — Enrichment or manual adaptation of AI descriptions according to ranges or brands

Human review of AI conversations
Manually review dialogues generated by virtual assistants, chatbots, or LLM models in order to correct errors, identify inconsistencies or detect unsafe or inconsistent behavior
Analysis of the conversational logic, the relevance of the answers and the adherence to instructions
Annotation of identified errors: hallucination, inadequate tone, confusion, broken thread...
Correction or reformulation suggestion (if post-treatment or active supervision)
Feedback to AI teams or integration of corrections into training datasets
Customer support — Reviewing AI dialogues with users to ensure clarity, politeness and efficiency
Education and e-learning — Review of AI exchanges to ensure pedagogical accuracy and language level
Deploying new AI agents — Systematic human QA phases before production

Content qualification
Assign metadata, labels, or ratings to content collected or generated (texts, images, audio extracts, videos) in order to make usable in an AI pipeline: training, filtering, prioritizing, or moderating.
Definition of qualification criteria (relevance, theme, language level, sound quality, etc.)
Human review of raw or generated content (visual, textual, audio...)
Assigning metadata or labels (e.g. trust level, theme, tone, intent, technical quality)
Reporting unusable or problematic content (e.g. noise, empty, off-topic, sensitive content)
Preparing datasets for LLMs fine-tuning — Qualification of prompt/response pairs according to their clarity or training value
Conversational analysis — Attribution of labels to AI dialogues: objective achieved, ambiguous response, consistent style...
Curation of data collected on the web or in business — Human sorting to keep only usable data

Content annotation for AI Red Teaming
Identify, classify and document potential flaws or undesirable behaviors of AI models, by structuring critical cases to assess and strengthen their robustness and security
Definition of critical test scenarios (malicious prompts, ambiguities, jailbreak attemps and prompt-injection techniques, adversarial prompts)
Generation of content by the AI model in these targeted scenarios
Human review and annotation of risky behaviors (hallucinations, illegal responses, explicit or implicit biases, circumvention of instructions, etc.)
Qualification of the severity and type of vulnerability detected (toxicity, security, reputation, compliance)
Assessment of the robustness of a model before production — Adversarial testing performed by trained evaluators
Ethical benchmark — Measuring the sensitivity of a model to certain types of prompts or sensitive contexts
Building Red Team test datasets — Creation of robust evaluation corpora from annotated outputs
Use cases
Ourcontent moderation and RLHF services support AI teams before deployment and inproduction. Typicalprojects include the following:

Why choose
Innovatiana?
Choose Innovatiana for managed content moderation and RLHF services delivered by trained, multilingual teams. We combine clear evaluation guidelines, domain expertise, multi-stage quality control and flexible workflows to help you improve model safety, alignment and performance.
Expert-led AI data delivery
Professional Data Labelers and AI Trainers, selected, trained and guided by experts to deliver reliable datasets for your AI projects.
From initial scoping to final delivery, we bring structure, consistency and quality oversight to every stage.
We defineyour objectives, data requirements and quality standards, taking into accountyour tools, timelines and constraints. Together, we establish the rightannotation approach and team for your project.
You receivea tailored proposal with a clear scope, delivery plan and project-basedpricing. Where needed, an initial pilot validates the approach and alignsexpectations before production begins.
A dedicated team prepares, annotates and reviews your data under expert supervision. Your Data Labeling Manager coordinates delivery, oversees quality and serves as your main point of contact throughout the project.
What our clients say
In an industry too often marked by opaque practices and insecure working conditions, Innovatiana stands out. The company has built an ethical, people-first approach to data labeling, recognising annotators as skilled experts who play an essential role in AI development. Their expertise is valued, their contribution is visible, and their work is at the heart of a more responsible and sustainable approach to AI.


Innovatiana helps us review and improve the datasets we use to train our machine learning models. With their support, we’ve reviewed over 50,000 annotations and reduced review time by 30%. The team is dedicated, reliable, and always ready to find solutions. I particularly appreciate the personal approach and direct communication with people who understand our needs and project constraints. I wholeheartedly recommend Innovatiana!


Innovatiana has annotated over 20,000 French property listings for us to train our text classification and recognition models. Their meticulous work achieved 98% compliance with our annotation guidelines, with 100% of batches delivered on time. We appreciate the quality of their work and the consistency of a team that knows our requirements well. Timelines are clearly defined, and communication is smooth throughout the project. We would gladly entrust them with future NLP or computer vision projects.


Several Innovatiana annotators work full-time as part of our team of surgeons and data scientists. Together, we have annotated over 67,000 images from more than 60 surgical procedures, covering around 30 categories of instruments. I value the team’s technical rigor and the commitment of the medical students supporting our projects. Their understanding of the medical context and attention to detail help us build high-quality datasets to train our AI models.


Innovatiana is part of the fourth cohort of our impact accelerator. Through its data annotation studio in Majunga, Madagascar, the company puts impact sourcing into practice: creating local jobs in communities with limited employment opportunities, recognising annotators’ expertise, and making transparency and fair working conditions central to its model. A concrete example of how the AI industry can create meaningful social impact.


At Innovatiana, ethical AI starts with respect for the people who make it possible. Fair working conditions, a supportive environment, and recognition of annotators’ expertise are central to the company’s approach. That investment in people is reflected in the care they bring to their work and the quality of the data they deliver. It shows how social responsibility and technical excellence go hand in hand.


Innovatiana shows that high-performing AI is built on a strong commitment to people. The company puts ethics into practice from the earliest stages of data preparation, recognising the essential role and expertise of its annotators. This is ethics by design, with respect for people at the heart of technological progress.


Innovatiana helped us annotate over 30,000 pipe inspection images across more than 50 classes, using a classification framework based on EN 13508-2. The project required careful image analysis and precise distinctions between closely related categories. The team was responsive, meticulous, and committed to understanding our technical requirements. We particularly valued the consistency of the annotations and the quality of the deliverables throughout this complex project.


Innovatiana sets a strong example for the data annotation industry, combining technical expertise, rigorous quality standards, and a clear commitment to ethical practices. They invest in their annotators through training, expert guidance, and fair, transparent working conditions. The result is an approach that values both the quality of the data and the people behind it.


🤝 Ethics is the cornerstone of our values
Content moderation and RLHF depend on skilled human judgment. We provide an ethical, high-impact solution built on fair employment, trained teams, transparent management and responsible handling of sensitive work.
Stable and fair jobs, with total transparency on where the data comes from
A team of trained Data Labelers who are fairly paid and supported in their professional growth
Flexible pricing by dataset or project, with no hidden costs
Economic development in Madagascar (and other countries) through training and local investment
Maximum protection of your sensitive data according to the best standards
Acceleration of global ethical and responsible Artificial Intelligence
Build Safer, Better-Aligned AI with Expert Human Feedback!

